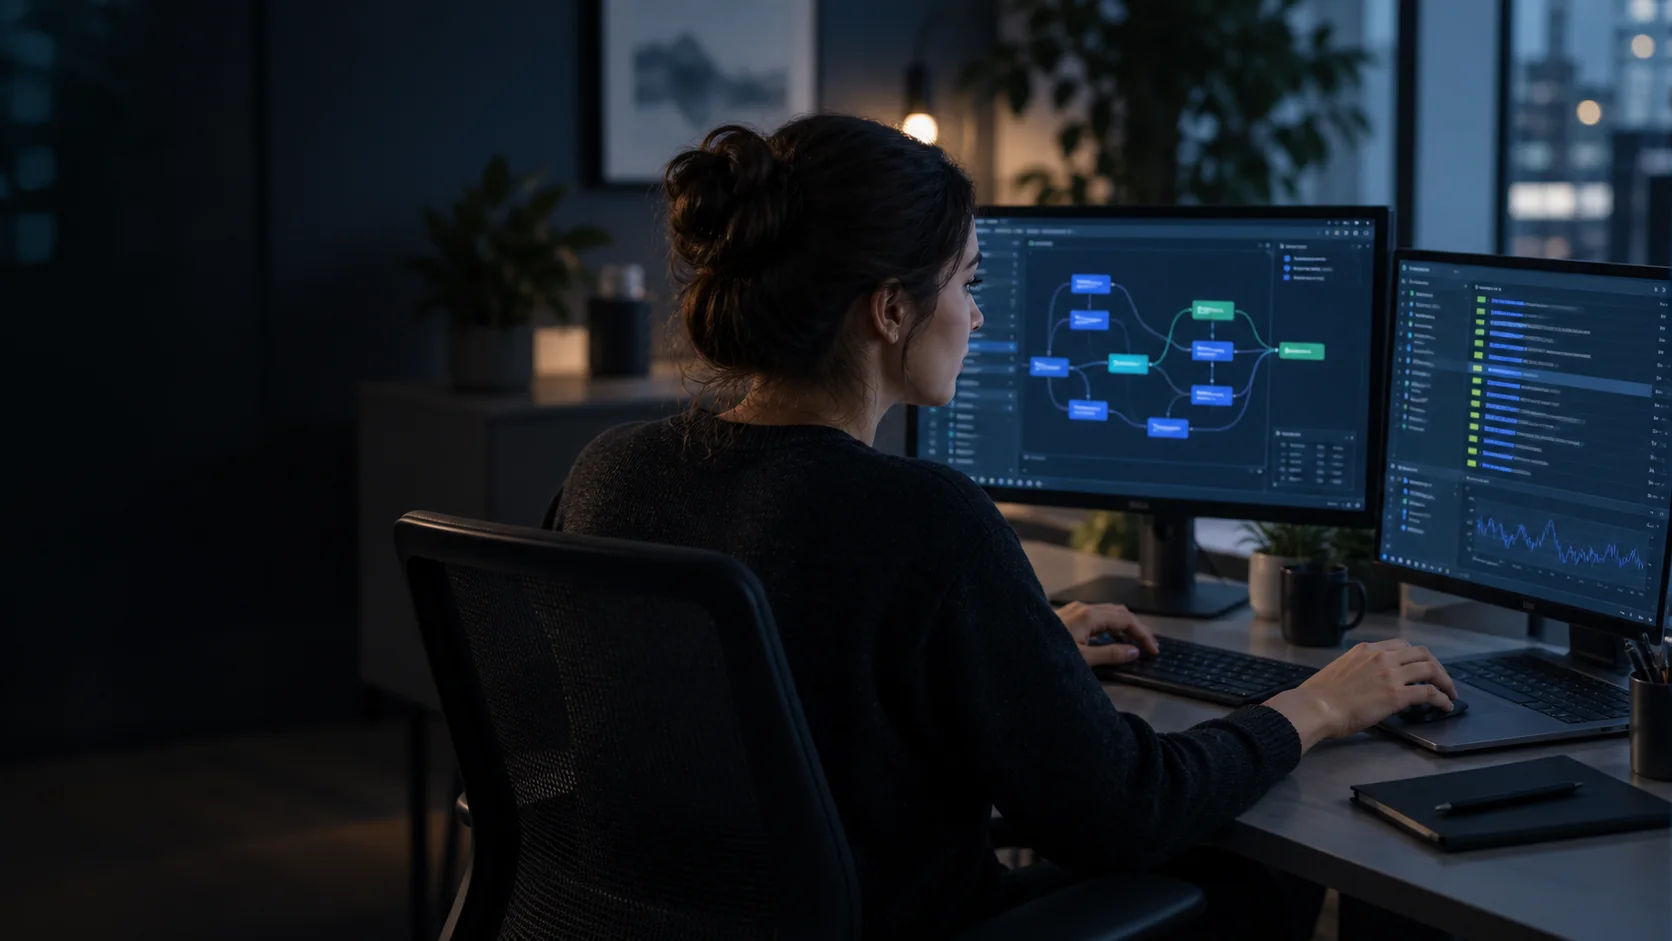
Data engineers monitoring resilient enterprise data pipelines

Data Pipelines Services

Pipelines rarely break because the code was wrong. They break because something upstream changed. We build for that expectation rather than against it.

What Data Pipelines Services Deliver

The Discipline

Data pipelines services build and operate the paths that move data from source systems into a platform where it can be used. The engineering is not conceptually difficult. What makes pipelines expensive is that they depend on systems whose owners have no obligation to tell you before changing them, so the failure mode is inherited rather than introduced, and it arrives without warning.
Our Approach

Pipelines are built assuming upstream change rather than stability. Schema evolution is handled explicitly, contracts are agreed with source owners where they exist, and every pipeline declares its expected freshness and volume so a silent failure becomes a loud one. Idempotency and replay are designed in, because a retry that duplicates records is worse than a failure that stops.

The Evidence

Fivetran's 2026 Enterprise Data Infrastructure Benchmark surveyed more than 500 data and technology leaders at organizations with 5,000 or more employees. It found that 53 percent of data engineering time now goes to keeping existing pipelines alive rather than building new capability, and that close to 30 percent of organizations report data project delays of a month or longer tied directly to pipeline maintenance and downtime.

Fivetran, 2026 Enterprise Data Infrastructure Benchmark

What does a pipeline engagement actually settle?

  1. Schema Change Behavior

    What happens when an upstream field is added, renamed or removed. Pipelines without an explicit answer fail on the third one, usually overnight and usually silently.

  2. Replay Position

    Whether a pipeline can be re-run for a past window without duplicating or losing records. Without idempotency, recovering from a bad day means a manual reconstruction nobody has time for.

  3. Freshness and Volume Expectation

    The declared window and record range for each pipeline, so a run that completes with a fraction of the expected data raises an alert rather than passing as successful.

Where Data Pipeline Work Usually Begins

  1. Maintenance Consuming the Team

    Engineers spend more of the week repairing existing pipelines than building new ones, and the ratio has been drifting in that direction for a year.

  2. Silent Partial Loads

    A pipeline completes successfully with a fraction of the expected records, and the shortfall is found in a report rather than by the platform.

  3. Schema Change Breakage

    An upstream team adds or renames a column and several downstream pipelines fail, usually with no advance notice and no contract to point at.

  4. Manual Export Dependency

    Data moves between systems as scheduled files and manual imports, so every downstream decision is made against yesterday at best.

  5. No Replay Path

    A bad day of data was loaded and correcting it requires a manual reconstruction, because the pipeline cannot safely be re-run for a past window.

  6. Freshness Nobody Can State

    Business users assume data is current, the pipeline runs nightly, and nobody has written down which is true.

  7. Point-to-Point Accumulation

    Each new requirement produced another bespoke script, and the estate now has more pipelines than anyone can inventory.

Why Choose Innogent Technologies for Data Pipelines Services

Why businesses build with Innogent
01

Built for Upstream Change

Schema evolution behavior is specified per pipeline: which changes are absorbed automatically, which raise an alert, and which halt the load. Pipelines built for a stable source are pipelines built for a source that does not exist.

Certifications

  • CMMI Level 5 Appraised
  • ISO 27001:2013
  • ISO 20000-1:2018
  • ISO 9001:2015
100+Projects Delivered
50+Global Clients
10+Years of Engineering Excellence

Data Pipeline Solutions We Build

  1. Batch Ingestion Pipelines

    Scheduled extraction and loading from databases, applications, files and APIs, with incremental strategies matched to what each source can actually support.

  2. Change Data Capture

    Log-based capture from operational databases, giving near-real-time replication without the query load that polling places on a production system.

  3. Streaming Pipelines

    Event ingestion and processing through Kafka or equivalent, where a genuine latency requirement justifies the operational addition.

  4. Transformation Pipelines

    Modeled transformation in the warehouse using dbt or Spark, with tests, documentation and lineage generated from the transformation code itself.

  5. Third-Party and API Ingestion

    Extraction from SaaS platforms and partner APIs, handling rate limits, pagination, authentication rotation and the undocumented behavior most of them have.

  6. Reverse ETL and Activation

    Pushing modeled data back into operational systems so the platform informs the workflow rather than only the dashboard.

  7. Pipeline Modernization

    Replacing accumulated bespoke scripts with a maintained framework, sequenced so the existing loads continue while each is migrated.

Pipeline Reliability Design

Pipeline reliability properties, implementation and prevented failures
PropertyWhat we implementWhat it prevents
Schema evolution handlingPer-pipeline policy on added, renamed, retyped and removed fields, with alerts for changes that need a humanOvernight failures from an upstream change nobody announced
IdempotencyDeterministic keys and merge semantics so re-running a window produces the same resultDuplicate records created by a retry, found weeks later in a reconciliation
Freshness and volume assertionsDeclared expectations checked on every run, with deviation raising an alertA successful run that loaded 4 percent of the expected records
Backfill and replayParameterized historical loads that can be run safely against productionManual reconstruction after a bad load, which is where most data incidents consume their time
Failure isolationOne failing source stopping only its own downstream models rather than the whole runA single unavailable API blanking an entire reporting layer
Retry and backoffBounded retries with backoff and dead-letter handling for records that cannot be processedSilent record loss, and retry storms against a source already under stress
Lineage emissionColumn-level lineage generated from transformation code as pipelines runImpact analysis before a change taking a week of manual tracing

Data Pipelines Scope, Timeline and Cost

Data pipeline engagements, coverage, timelines and delivery teams
EngagementWhat it coversTimelineTeam
Pipeline AssessmentInventory of existing pipelines, failure history, maintenance burden, schema change exposure and a prioritized remediation plan2 to 3 weeks1 architect, 1 data engineer
Core Ingestion BuildIngestion from a defined source set with schema handling, assertions, orchestration and alerting6 to 12 weeks2 to 4 data engineers
Streaming or CDC ImplementationLog-based capture or event streaming where latency requirements justify it, including replay and ordering guarantees8 to 16 weeks3 to 5 engineers, 1 platform engineer
Transformation LayerModeled transformation with tests, documentation and lineage, built on dbt or Spark6 to 12 weeks2 to 4 analytics engineers
Pipeline ModernizationReplacing bespoke scripts with a maintained framework, migrated one source at a time with the existing loads running10 to 20 weeks3 to 5 engineers
Ongoing Pipeline OperationsMonitoring, schema change response, source onboarding and continued transformation workOngoingSized to source count

What Determines Data Pipelines Cost

Cost depends on the requirement: the number of sources and how many expose a usable extraction interface, the volume and latency required, whether change data capture is possible against production systems, how much transformation logic must be recovered from existing scripts, and whether the sources are cooperative enough to agree schema contracts. Innogent Technologies issues an estimate after pipeline assessment.

Why the Source Determines the Estimate

A pipeline from a documented API with stable schemas and a responsive owning team is a week of work. The same volume of data from a legacy system with no interface, undocumented nulls and an owner who left the business is a different engagement entirely. Source condition, not target complexity, is the variable that separates an estimate from an outcome, and it is established by profiling rather than by asking.

Our AI-Enabled Data Pipeline Process

  1. Step 1

    Source Profiling

    Every source profiled for schema stability, volume, update behavior, extraction constraints and data quality. AI-assisted profiling across large source estates

    1 to 3 weeks
  2. Step 2

    Contract and Design

  3. Step 3

    Framework Foundation

  4. Step 4

    Build

  5. Step 5

    Validation

  6. Step 6

    Operate

Technology Stack for Data Pipelines

  1. 01

    Managed ingestion

    • Fivetran
    • Airbyte
    • Stitch
    • Native cloud connectors
  2. 02

    Change data capture

    • Debezium
    • AWS DMS
    • Qlik Replicate
    • Native database CDC
  3. 03

    Streaming

    • Apache Kafka
    • Amazon Kinesis
    • Google Pub/Sub
    • Apache Flink
    • Spark Structured Streaming
  4. 04

    Transformation

    • dbt
    • Apache Spark
    • SQL
    • Python
    • Pandas and Polars
  5. 05

    Orchestration

    • Apache Airflow
    • Dagster
    • Prefect
    • AWS Step Functions
  6. 06

    Targets

    • Snowflake
    • BigQuery
    • Databricks
    • Redshift
    • Synapse
    • PostgreSQL
    • S3 and object storage
  7. 07

    Quality and lineage

    • dbt tests
    • Great Expectations
    • Soda
    • OpenLineage
    • Monte Carlo
  8. 08

    Reverse ETL

    • Hightouch
    • Census
    • Custom activation services

Data Pipelines FAQs

Answers about pipeline delivery, cost, ETL and ELT, streaming, schema evolution, replay and connector strategy.

What are data pipelines services?

Data pipelines services build and operate the paths that move data from source systems into a platform where it can be used. Innogent Technologies builds pipelines on the assumption that upstream systems will change without notice, with explicit schema evolution policy, declared freshness and volume expectations, and replay capability designed in from the start.

How much do data pipelines services cost?

Cost depends on the requirement: the number of sources and whether each exposes a usable extraction interface, the volume and latency required, whether change data capture is possible against production systems, how much transformation logic must be recovered from existing scripts, and whether source owners will agree schema contracts. Innogent Technologies estimates after pipeline assessment.

How long does it take to build data pipelines?

A pipeline assessment runs 2 to 3 weeks. Core ingestion from a defined source set takes 6 to 12 weeks, a transformation layer 6 to 12 weeks, and streaming or change data capture implementation 8 to 16 weeks. Replacing an estate of bespoke scripts with a maintained framework runs 10 to 20 weeks.

What is the difference between ETL and ELT?

ETL transforms data before loading it into the target. ELT loads raw data first and transforms it inside the warehouse, which is now the more common pattern because warehouse compute is cheap and raw data is worth retaining for reprocessing. Innogent Technologies uses ELT by default and ETL where volume, cost or sensitivity makes transforming before loading the better answer.

Do we need streaming or is batch enough?

Batch is enough for most reporting requirements and carries materially lower operational cost. Streaming is warranted by a genuine latency requirement, such as operational decisions made in seconds or event-driven downstream systems. Innogent Technologies asks what decision requires the latency before recommending a streaming architecture.

What happens when a source system changes its schema?

Behavior is specified per pipeline in advance: which changes are absorbed automatically, which raise an alert for a human to review, and which halt the load. Pipelines built without this policy fail on the third schema change, typically overnight and typically without anyone noticing until a report is wrong.

Can a pipeline be re-run for a past date?

Yes, where idempotency is designed in. Every pipeline Innogent Technologies builds uses deterministic keys and merge semantics so a window can be re-processed without duplicating or dropping records. Without this, correcting a bad load becomes a manual reconstruction, which is where most data incidents spend their time.

Should we build connectors or buy them?

Buy for standard sources. Maintaining a hand-written connector for a major SaaS platform is a permanent commitment with no differentiating value, and managed connectors handle the authentication rotation, rate limiting and schema drift that consume the time. Custom extraction is reserved for sources that genuinely have no supported option.

Start Your Data Pipeline Engagement

A short call establishes what sources you depend on, what breaks and how often, and whether the constraint is reliability, coverage or the maintenance burden the current estate carries.

  • Onboard in 48-72 Hours

  • Start With a Trial Sprint

  • 10+ Years of Engineering Expertise

  • Experience Across Global Markets

Get in Touch

Bring us your ideas, your toughest challenges, or just a blank canvas. We can make it work and excel together.

Fields marked * are required.