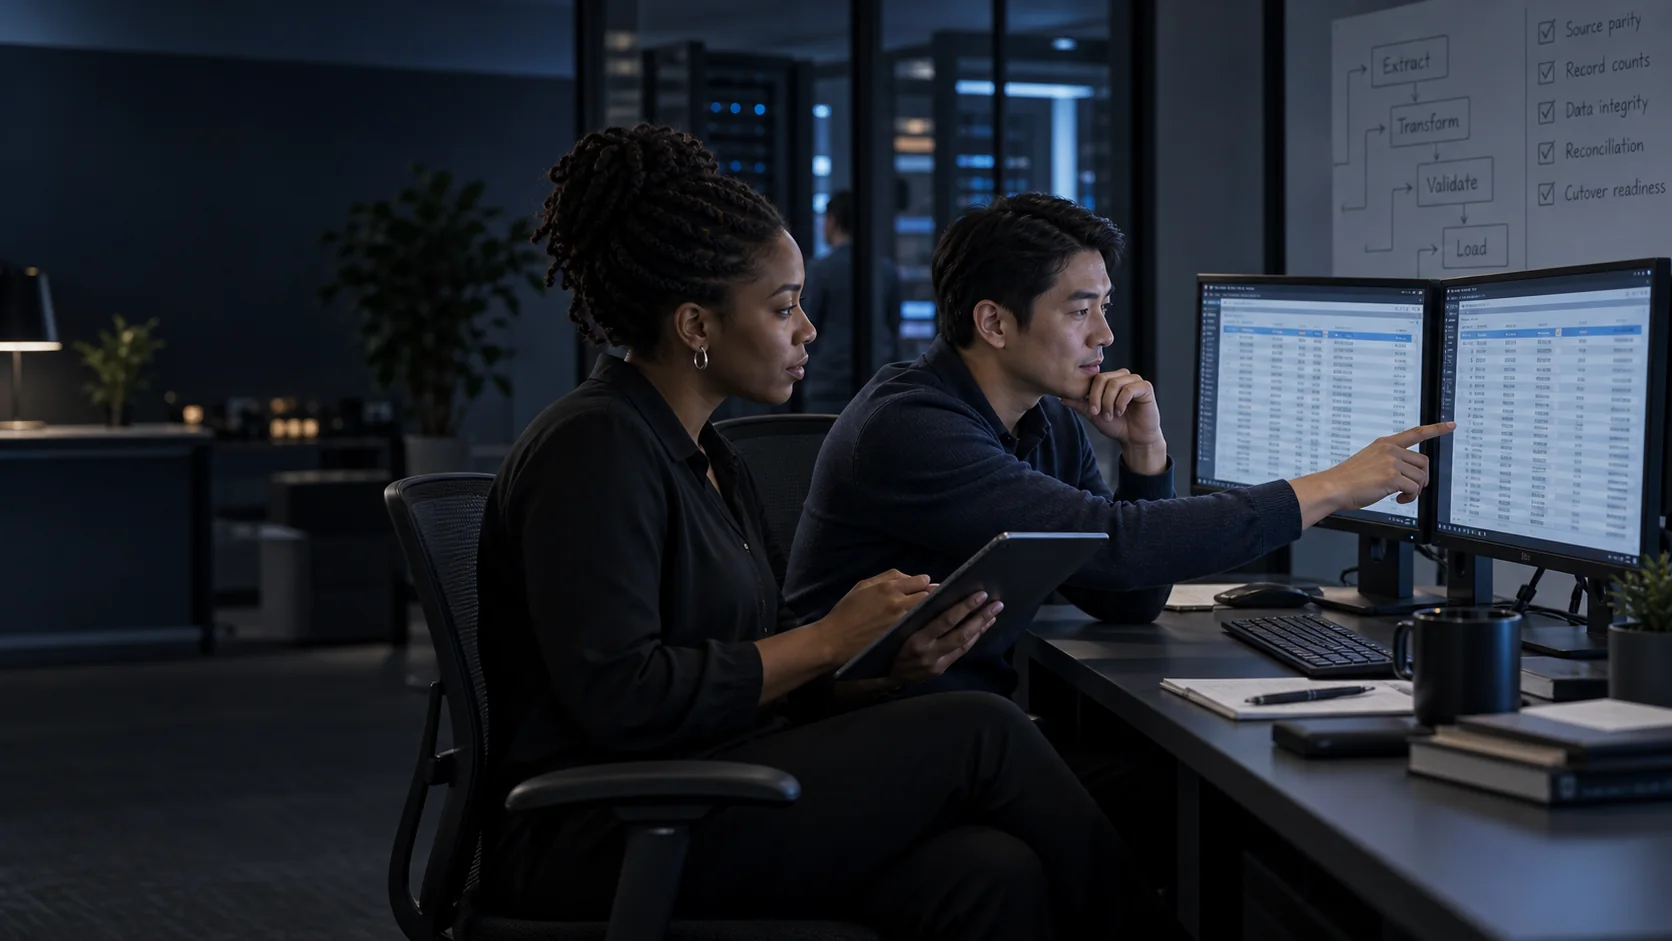
Data engineers designing a trusted enterprise data platform

Data Engineering Services

A dashboard nobody believes is worse than no dashboard. We build the pipelines, models and controls that make data trustworthy enough to act on.

What Data Engineering Services Deliver

The Discipline

Data engineering services build the systems that move, store, model and validate data so it can be used for reporting, operations and machine learning. The technical work is well understood. What is harder, and what most platforms fail on, is trust: an organization will route around a data platform it does not believe, and once that happens the platform costs money without changing a single decision.
Our Approach

We build for the questions the business is actually trying to answer, then work backwards to the models, pipelines and sources that support them. Quality controls, ownership and lineage are designed in rather than added once someone disputes a number, because that dispute is where platform credibility is usually lost for good.

The Evidence

dbt Labs surveyed 459 data practitioners and leaders for its 2025 State of Analytics Engineering report. Poor data quality remained the most frequently reported challenge, cited by 56 percent of respondents. Investment priorities told the same story from the other direction: 45 percent named AI tooling as their top area of spend and 38 percent named data quality and observability.

dbt Labs, 2025 State of Analytics Engineering

What does a data engineering engagement actually settle?

  1. Ownership Per Dataset

    Which team is accountable for the correctness of each dataset, and who is called when it is wrong. Platforms without this produce disputes that get resolved by whoever is most senior rather than by whoever is right.

  2. Definition Authority

    Where a business metric is defined once, so two reports cannot disagree about revenue. Estates that define metrics in the reporting layer define them repeatedly and inconsistently.

  3. Freshness Contract

    How current each dataset is guaranteed to be, stated rather than assumed. Decisions made on data believed to be live but refreshed nightly are the most expensive class of data error because nobody detects them.

Why Choose Innogent Technologies for Data Engineering Services

Why businesses build with Innogent
01

Built Backwards From the Decision

Design starts with the questions the business needs answered and works back to sources. Platforms designed forwards from available data produce impressive coverage of things nobody asked about.

Certifications

  • CMMI Level 5 Appraised
  • ISO 27001:2013
  • ISO 20000-1:2018
  • ISO 9001:2015
100+Projects Delivered
50+Global Clients
10+Years of Engineering Excellence

Data Engineering Services We Provide

Where Data Platforms Lose Trust

Trust in a data platform is lost in identifiable ways, and almost never recovered by adding capability. These are the failures that matter more than coverage.

  1. The Disputed Number

    Two reports disagree and nobody can say which is right, because the metric is defined in both places rather than once. After this happens twice, stakeholders start keeping their own spreadsheet.

  2. The Silent Staleness

    A pipeline fails, the dashboard keeps rendering yesterday's data, and a decision is made on it. Failure that produces an error is recoverable; failure that produces plausible old numbers is not.

  3. The Unexplained Change

    A figure moves and nobody can explain whether the business changed or the pipeline did. Without lineage and change history, that question takes days and the answer arrives after the decision.

  4. The Unowned Dataset

    A table everyone depends on and nobody maintains. It works until an upstream schema changes, at which point it becomes urgent and ownerless simultaneously.

  5. The Stakeholder-Reported Incident

    The business tells the data team the data is wrong. Every occurrence transfers a little credibility from the platform to the spreadsheet the stakeholder built instead.

  6. The Undocumented Definition

    Nobody can say exactly what active customer means, so each team applies its own filter and the numbers diverge legitimately, which is harder to fix than a bug.

Our AI-Enabled Data Engineering Process

Data engineering process stages

Question Definition

The decisions the platform must support, the metrics behind them and their agreed definitions, established with the business before any source is connected

1 to 2 weeks

Technology Stack for Data Engineering

  1. 01

    Ingestion and integration

    • Fivetran
    • Airbyte
    • Debezium
    • Kafka Connect
    • Custom extractors
  2. 02

    Transformation

    • dbt
    • Apache Spark
    • SQL
    • Python
    • Dataform
  3. 03

    Orchestration

    • Apache Airflow
    • Dagster
    • Prefect
    • Native cloud schedulers
  4. 04

    Storage and compute

    • Snowflake
    • BigQuery
    • Databricks
    • Amazon Redshift
    • Azure Synapse
    • PostgreSQL
  5. 05

    Streaming

    • Apache Kafka
    • Kinesis
    • Pub/Sub
    • Flink
    • Spark Structured Streaming
  6. 06

    Quality and observability

    • dbt tests
    • Great Expectations
    • Soda
    • Monte Carlo
    • OpenLineage
  7. 07

    Cataloging and governance

    • DataHub
    • OpenMetadata
    • Collibra
    • Unity Catalog
    • Column-level lineage
  8. 08

    Semantic and consumption

    • dbt Semantic Layer
    • Cube
    • Looker
    • Power BI
    • Tableau
    • Metabase

Data Engineering FAQs

Answers about data engineering, platform cost and timelines, data quality, architecture choices and existing platform modernization.

What are data engineering services?

Data engineering services build the systems that move, store, model and validate data so it can be used for reporting, operations and machine learning. Innogent Technologies designs backwards from the decisions the business needs to make, and builds quality controls, dataset ownership and freshness contracts in from the start rather than adding them once a number is disputed.

How is data engineering different from data analytics?

Data engineering builds and operates the platform that makes data available and trustworthy. Data analytics uses that data to answer questions and inform decisions. Analytics built on an unreliable platform produces confident answers that are wrong, which is worse commercially than having no answers.

How much do data engineering services cost?

Cost depends on the requirement: the number and condition of source systems, how much data requires remediation before use, whether metric definitions already exist and are agreed, the freshness the business genuinely needs, and the compliance obligations attached. Innogent Technologies estimates after source assessment.

How long does it take to build a data platform?

Question definition runs 1 to 2 weeks, source assessment 2 to 3 weeks and architecture and modeling a further 2 to 3. Build duration depends on source count and data condition, with validation adding 2 to 3 weeks. Innogent Technologies commits to a schedule after source assessment rather than before the sources have been profiled.

Why do data platforms end up unused?

Because trust is lost in specific ways: two reports disagree, a failed pipeline serves stale data silently, a figure changes and nobody can explain why, or the business finds the error before the data team does. Each occurrence moves a stakeholder closer to keeping their own spreadsheet, and adding capability does not reverse it.

Do we need a data warehouse, a lakehouse or a data mesh?

Usually less than the market suggests. A warehouse with scheduled transformation answers most reporting requirements at a fraction of the operational cost. Lakehouse and mesh architectures address specific problems of scale, format diversity and organizational structure, and Innogent Technologies recommends them only where those problems are present.

How do you handle data quality?

Freshness, volume, schema and business-rule tests run as part of the pipeline, with failures blocking downstream propagation rather than appearing in a report. Every dataset carries a named owner, a documented definition and a stated freshness guarantee, which is what turns a disputed number into a question rather than an argument.

Can you work with our existing data platform?

Yes, and it is the common case. Engagements frequently begin by assessing an existing warehouse or pipeline estate, establishing where trust has been lost and remediating that before extending coverage. Replacing a platform is occasionally correct and more often the expensive answer to a quality problem.

Start Your Data Engineering Engagement

A short call establishes what decisions the data is meant to support, whether the business currently trusts the numbers it has, and where the platform is losing credibility.

  • Onboard in 48-72 Hours

  • Start With a Trial Sprint

  • 10+ Years of Engineering Expertise

  • Experience Across Global Markets

Get in Touch

Bring us your ideas, your toughest challenges, or just a blank canvas. We can make it work and excel together.

Fields marked * are required.